Kalman Linear Attention:
Parallel Bayesian Filtering For Efficient Language Modelling and State Tracking
Overview
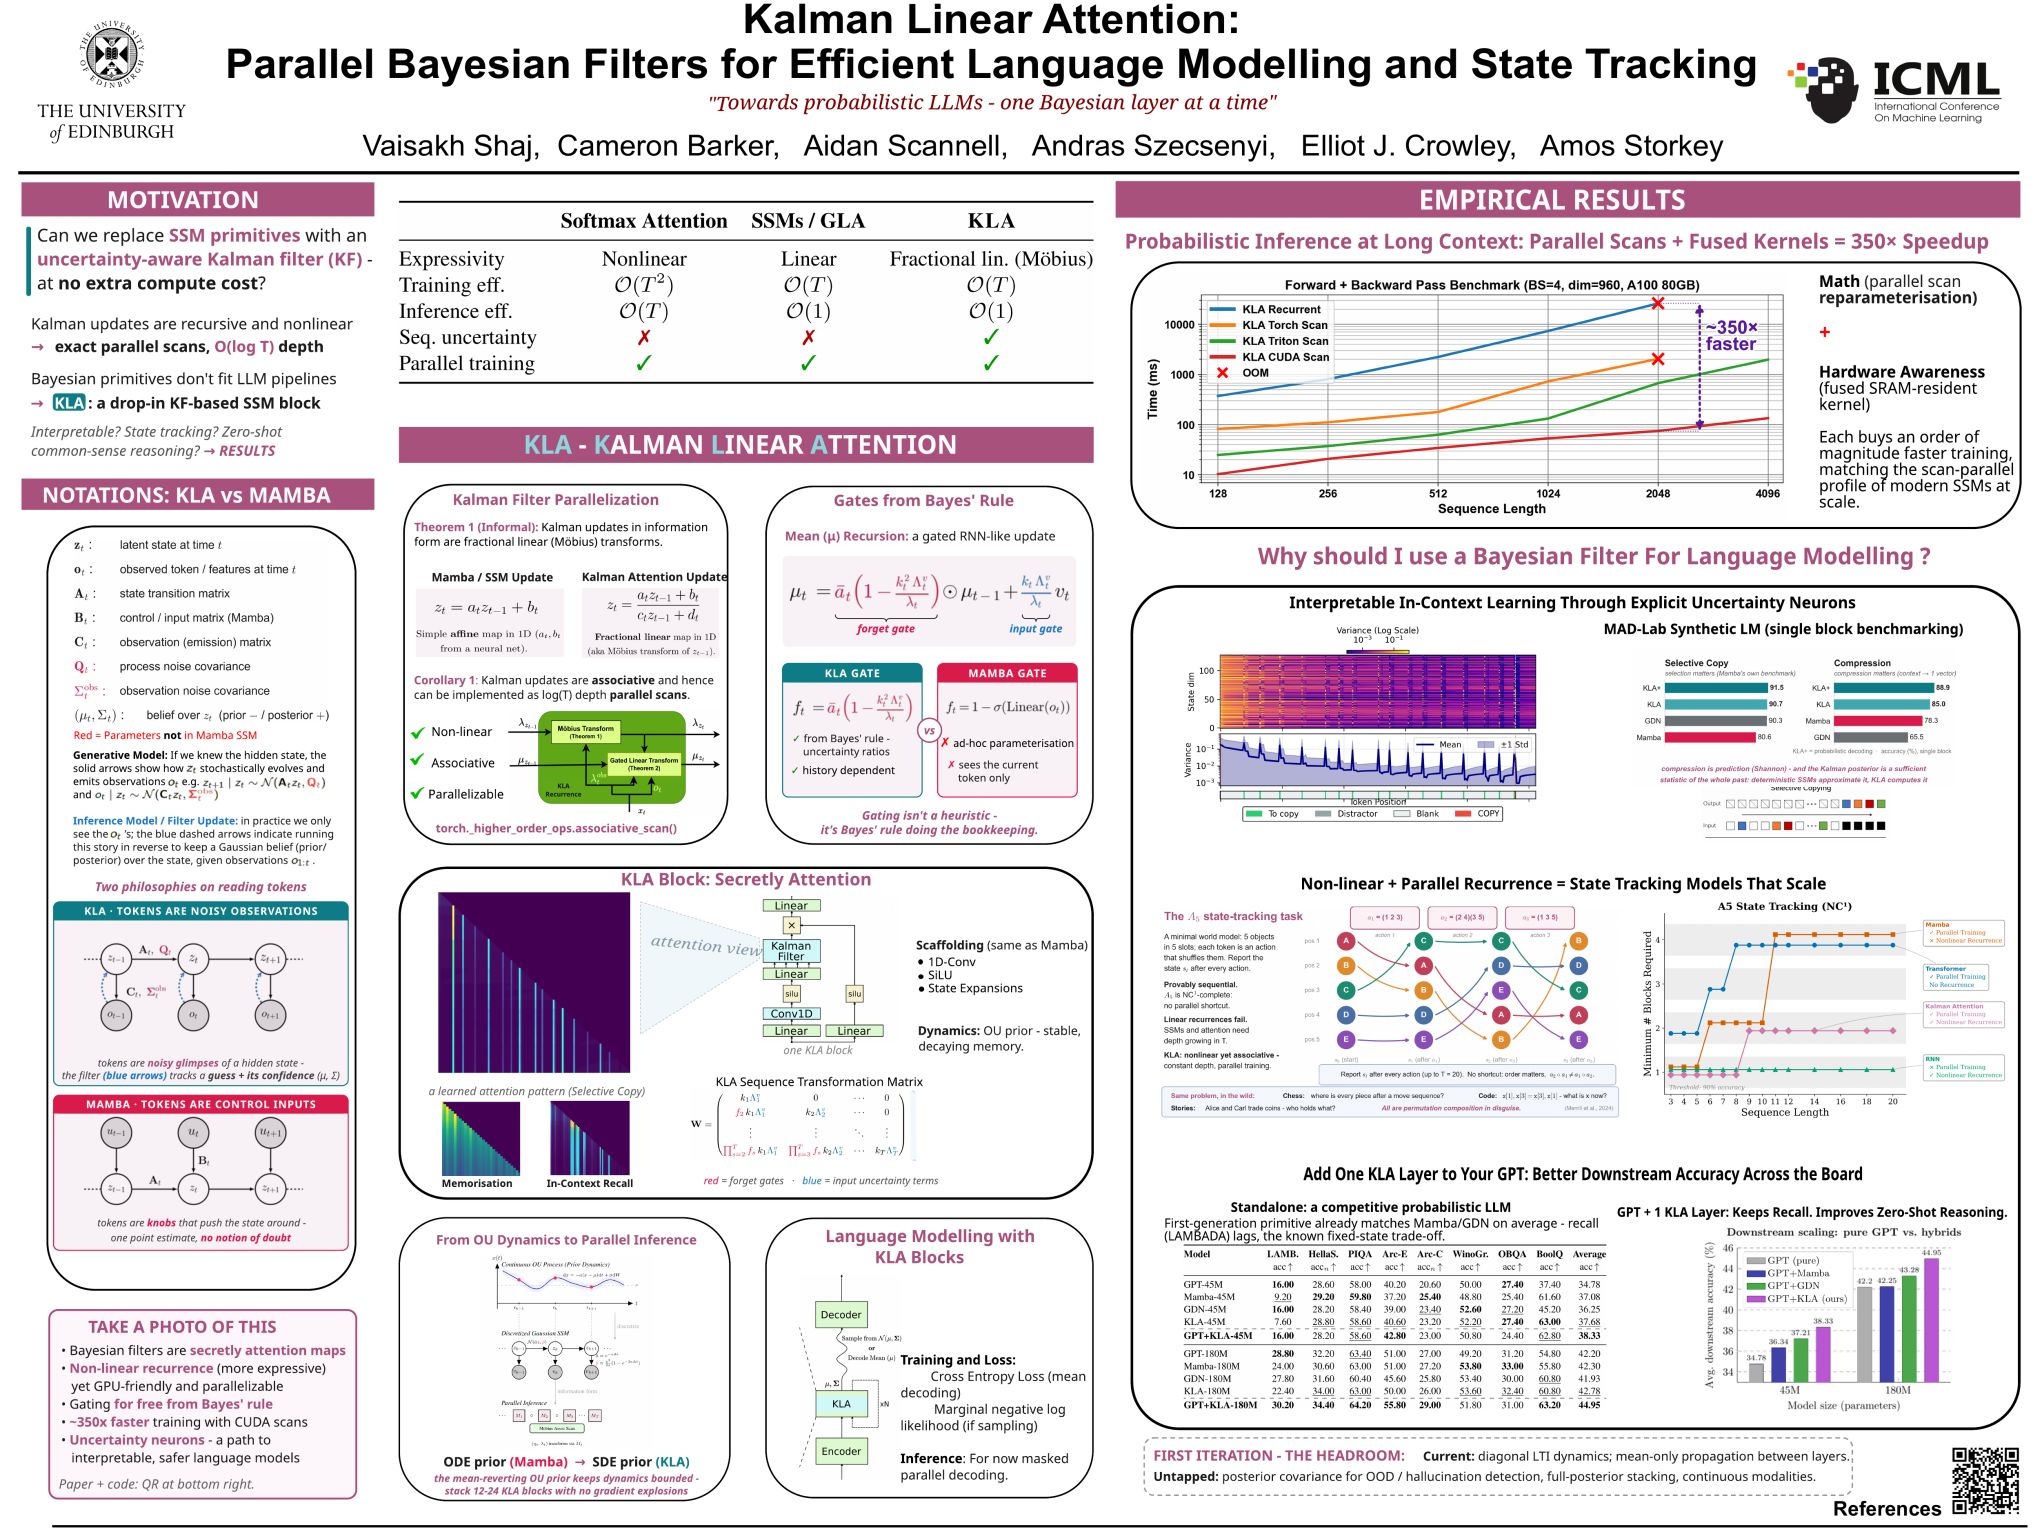
Kalman Linear Attention (KLA) brings Bayesian filtering into language models. It maintains a state estimate and its uncertainty, using both to decide how much information to retain and how much to learn from each new token. We reformulate the Kalman filter’s nonlinear updates as associative scans, enabling parallel training with computation that grows linearly with sequence length.
KLA improves state tracking while remaining competitive with modern state-space models on language-modelling benchmarks. It also complements attention: replacing the final attention layer of a 180M-parameter GPT with KLA raises average zero-shot accuracy across eight benchmarks from 42.20% to 44.95%.
Poster